Data annotation

A bench of 650, a written guide, and a test nobody skips.

Foundry is where the work happens: transcribers who write what was actually said, aligners who put a timestamp on every word, reviewers who sample and score every batch. Audio is the deepest line on the bench. Image, video and text run through the same gate.

Two crafts, both running today
250
Transcribers — 50 on fixed-term contracts
400
Word aligners on the freelance bench
9
Locales worked in today, more on request
95%+
QA-sample accuracy, checked against WER
Transcription3,000+ hours

50 on fixed-term contracts, the rest freelance — and hiring against every open sector.

Word alignment1,000+ hours

Freelance bench, timestamped to the word so a model can be scored on when it heard something, not just what.

Data types

Any data type, one calibration gate.

The guide, the training module and the test are the same shape whatever the file is. Every project gets a gold set, a calibration pass before paid work, and QA sampling scored against the guide.

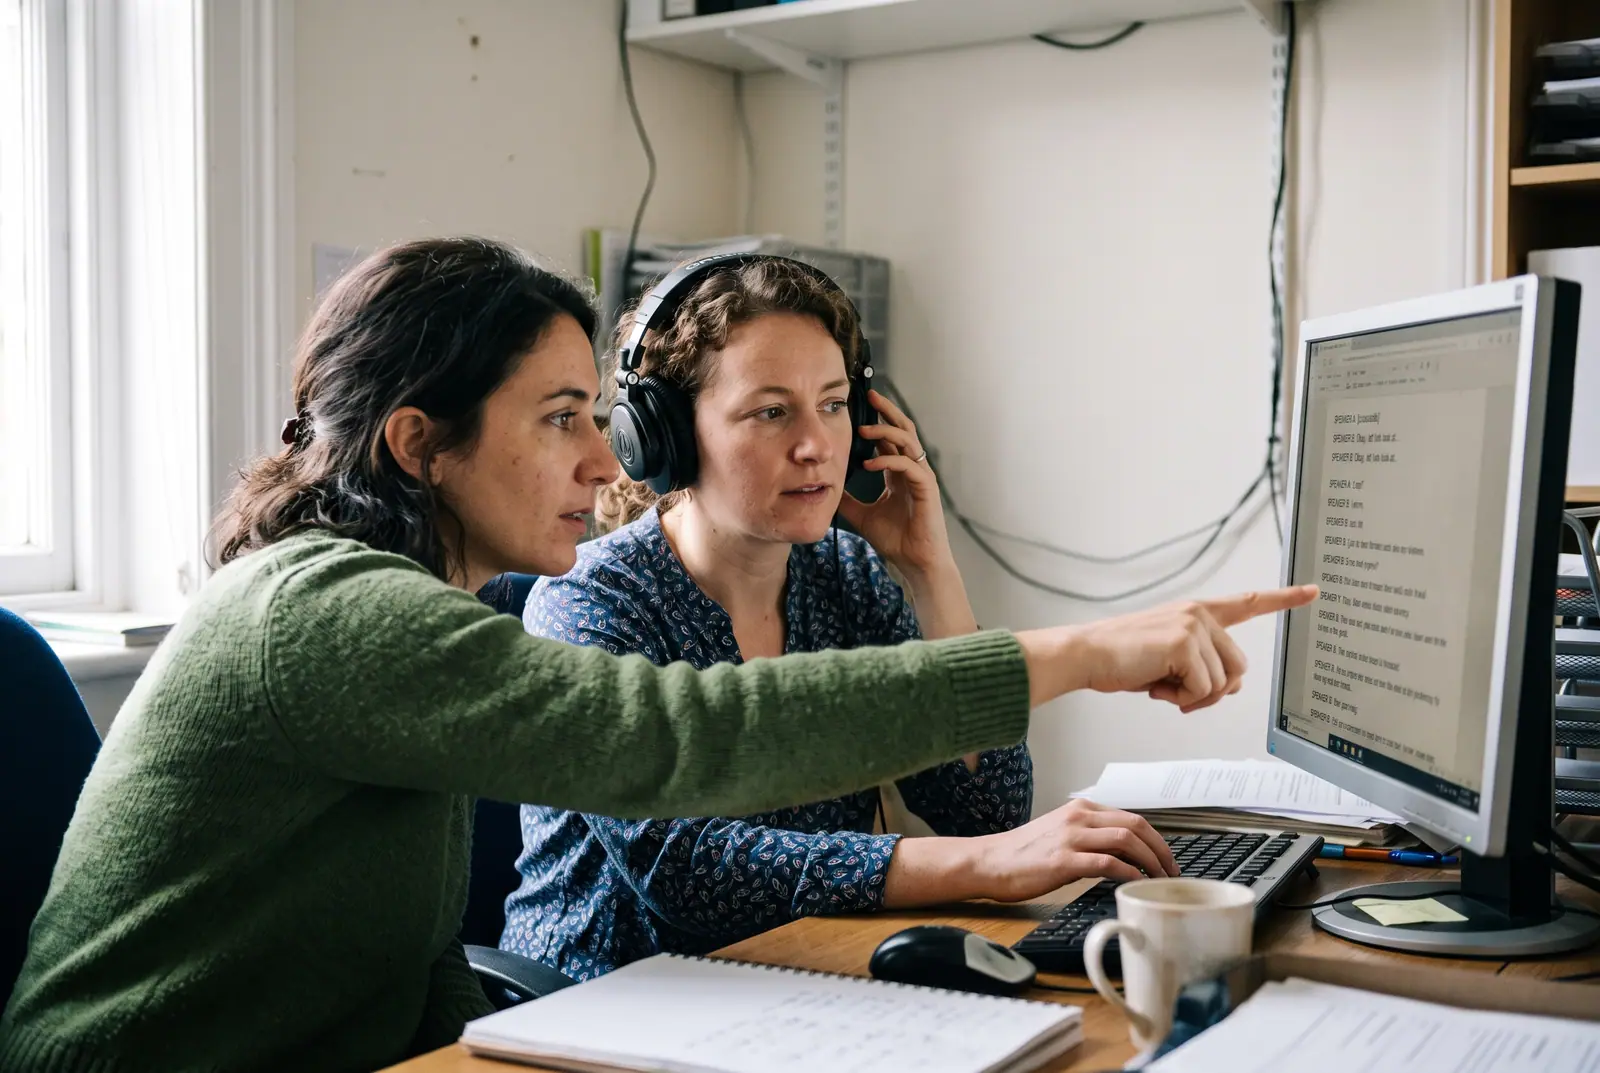
A transcriber working at a laptop with headphones, a waveform on screenAn aligner adjusting word-level timestamp boundaries on a waveformTwo reviewers checking a transcript together on one screen

Audio

Verbatim transcription, word-level alignment, speaker attribution and entity spans, to one written convention per project.

  • Verbatim transcription — fillers, repeats and false starts kept
  • Word alignment: start and end on every word
  • Speaker turns and diarization
  • Entity and intent spans on the tokens that carry the transaction
3,000+ hours transcribed · 1,000+ hours aligned · 95%+ QA-sample accuracy
An annotator drawing bounding boxes around products on a shelf photographAn annotator tracing a segmentation mask around an object with a stylusAn annotator extracting highlighted fields from a photographed receipt

Image

Boxes, polygons, masks and attributes, with the guide and the gold set that make two annotators land on the same answer.

  • Bounding boxes and polygons
  • Segmentation masks
  • Attribute and classification labels
  • Document and receipt field extraction
Gold set per project · agreement and rework rate reported per batch
An annotator marking sub-task segments on a video timelineAn annotator adjusting object-tracking boxes across video framesTwo reviewers adjudicating a success label on a robot episode

Video

Temporal segmentation, tracking and captions — including the embodied tasks on the Physical Intelligence pages.

  • Task and sub-task boundaries
  • Object tracking across frames
  • Natural-language captions per segment
  • Success and failure labels per episode
Episode-level labels · reviewers stream the clip, never download itSee Physical Intelligence
A grader comparing two model replies side by side against a printed rubricEntity and intent spans being highlighted in a call transcriptA grader ticking rubric criteria on paper beside a transcript on screen

Text

Preference judgments, rubric scores and span labels by people who work in the sector, against a rubric a stranger can apply.

  • Pairwise preference and rubric scoring
  • Entity and intent spans
  • Classification to a sector taxonomy
  • Red-team and policy labels
Practitioner graders · rubric written with an operator from the sector
Before anyone is paid

Nobody starts on production work.

Every annotator clears the same gate, on every project, however long they have been on the bench.

Join the bench on Foundry
  1. 01day 0
    Read the guide

    One written convention per project — casing, tags, how a number is written out, what counts as an edge case. Versioned; the version ships with the batch.

  2. 02day 0–1
    Training module

    About thirty samples with the answers visible, so the guide stops being abstract before anyone is paid for it.

  3. 03day 1–2
    Testing module

    A held-back set, graded against the guide. No pass, no production access — the test can be retaken after re-reading, not after arguing.

  4. 04ongoing
    Production, sampled

    Work goes out with QA sampling behind it. Below threshold routes back to calibration, and rejected work is not billed to the customer.

What arrivesWhat lands in your bucket.
  • 01Labels in the agreed schema — JSON, with CSV or text mirrors
  • 02Guide version and reviewer chain on every batch
  • 03Quality report: QA-sample accuracy, WER where audio, agreement, rework rate
  • 04Gold-set results per annotator, on request
  • 05Rework before delivery, never on your invoice
From standard to score

How a rubric gets built.

A rubric is not a list of nice qualities. It is what one operator checks before they call a call handled, written so that a stranger reaches the same verdict.

  1. 013–5 days
    Capture the standard

    We sit with an operator and write down what they check before they call a call handled. That list is the rubric's first draft.

  2. 021 week
    Make it applicable

    Every criterion is rewritten until two strangers grading the same call land on the same score.

  3. 033–7 days
    Build the verifier

    The mechanical criteria become a function returning a score in [0,1]. Judgment criteria stay with people, and we say which is which.

  4. 04on delivery
    Ship with the quality report

    Nothing is delivered without the numbers it was produced at: QA-sample accuracy, WER against the adjudicated reference, inter-annotator agreement, and what was reworked.

Sample rubric · BankingCard dispute · caller reports two charges they do not recognise
4 must · 2 should
  • Verified identity before discussing any transactionmust
  • Captured both amounts and both merchant names, read back oncemust
  • Stated the provisional-credit timeline without inventing a datemust
  • Did not promise a refund outcomemust
  • Offered card replacement when fraud pattern was presentshould
  • Closed with the reference number, spoken slowlyshould

Two strangers, same call, same score — or the criterion gets rewritten. Agreement on every criterion is measured and reported per batch.
Quality system

What keeps the number honest.

  1. 01A guide before a keystroke

    Every project starts from one written convention, agreed with the customer and versioned. Disagreement about what a tag means is a guide bug, and it gets fixed in the guide.

  2. 02Calibrate, then produce

    Training on about 30 samples, then a held-back test graded against the guide. Nobody reaches paid production work without clearing it.

  3. 03Three measures, all reported

    Delivered batches carry accuracy against the guide on a QA sample, WER against an adjudicated reference, and inter-annotator agreement on the double-passed portion. All three ship with the batch, whether they flatter us or not.

  4. 04Agreement is a schema signal

    When IAA drops on a task, we treat it as the guide being ambiguous before we treat it as an annotator being wrong. Agreement is measured per batch and per reviewer, so drift shows up as a trend rather than a surprise.

  5. 05Rework is ours, not yours

    Work below threshold is redone before delivery and is not billed. The rework rate goes in the batch report, because hiding it would make the accuracy number meaningless.

  6. 06Benchmark references are double-passed

    Customer delivery is QA-sampled. Benchmark reference transcripts are stricter: written twice, independently, with a senior reviewer adjudicating every disagreement — nothing else is defensible as a scoring baseline.

The bench

Who annotates, and what they had to clear.

Nobody touches production data before passing a calibration set. Reviewers are re-checked against that same set every week — graders drift too, and measuring it is the only way to catch it.

RoleBar to enterWhat they do
AnnotatorSector experience, passes a calibration set before touching production dataTranscription, entity spans, turn boundaries, preference judgments
ReviewerSustained QA-sample accuracy above threshold, across batchesSecond pass, adjudication on disagreement, agreement reporting, batch sign-off
Rubric authorPractising operator — the person who would sign off on this call at workWrites what a good answer is, in criteria a stranger can apply
Calibration leadReviewer who has held threshold while running a guide revisionWeekly reviewer checks, gold-set maintenance, guide revisions
Questions

Before you send a batch.

Is Foundry your own?
Yes. It is the workspace the bench runs on — guidelines, training and testing modules, production queues and QA sampling — and the same platform contributors sign in to.
How is quality measured?
Delivered batches are sampled and scored against the guide, and against an adjudicated reference for WER where the data is audio. Both numbers, plus inter-annotator agreement and the rework rate, ship with the batch.
Can you annotate data we already have?
Yes — most annotation work is on customer audio, images or video. It is pinned to your region and graders stream it rather than copy it.
Who writes the guide?
We do, with your team, and a practising operator where the labels need sector judgement. Every criterion has to be one two strangers apply the same way.

Send a sample, get it back labelled.

Ten minutes of audio, a hundred images or a page of text, and your guide if you have one. It comes back annotated within five working days with the agreement report, so you can judge the bench on your own data before anything is scoped.

Send us a sample