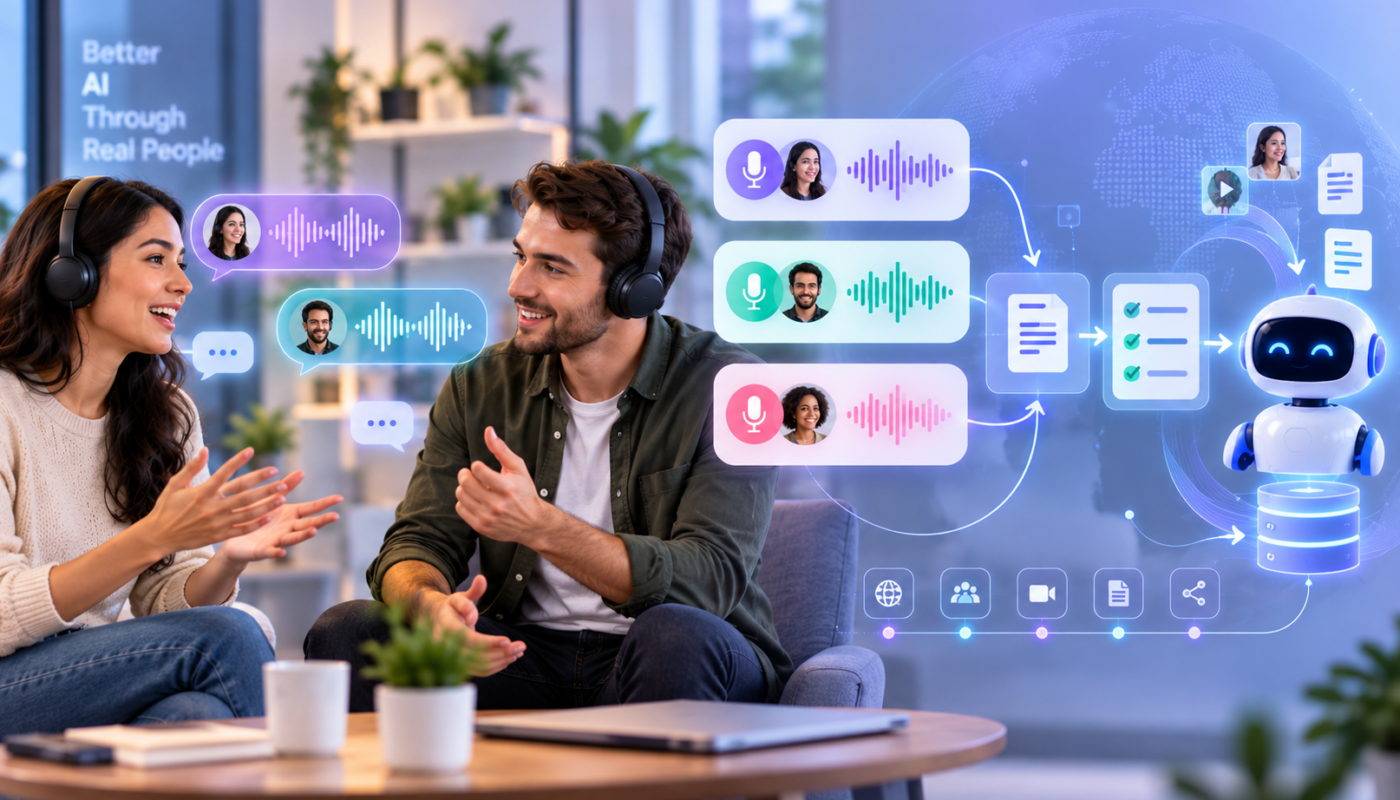
Every voice model that sounds natural today was trained on conversations that started out messy — cross-talk, filler words, half-finished sentences. Turning that raw audio into usable training data is most of the work, and almost none of it is glamorous.
Why raw audio isn’t enough
A model trained only on clean, scripted speech learns to sound clean and scripted. Real usefulness comes from exposure to how people actually talk: interruptions, corrections, regional accents, and the small verbal tics that make speech recognizable as human.
Collection
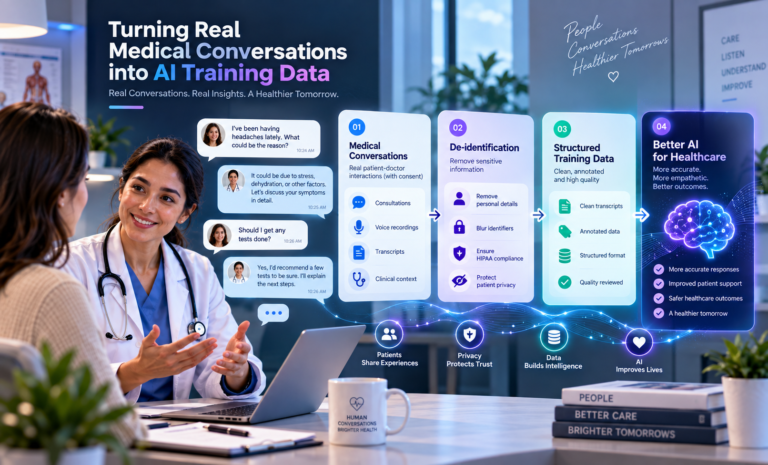
Contributors record or submit real conversations under a clear consent and compensation model. Every clip is tagged with metadata — language, accent, recording condition — before it ever reaches an annotator.
Transcription
Human transcribers, not just ASR, produce the ground truth. Automated transcription gets a first pass, then a person corrects it against the audio, which is where most of the quality actually comes from.
Grading and alignment
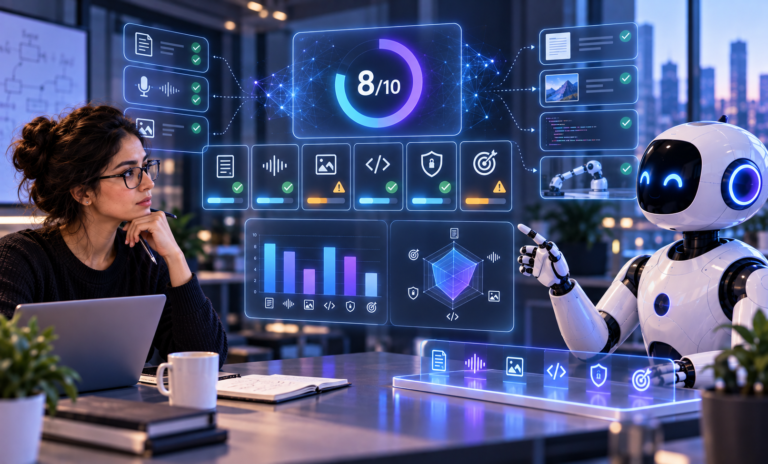
A second pass grades the transcript against a rubric — intelligibility, naturalness, whether the emotional tone matches the audio. Only clips that clear the bar go into a training set.
What this means for model builders
Teams that license this kind of graded, human-verified data consistently ship voice models that generalize better to real users, simply because the training distribution already looks like the deployment distribution.
Where this is headed
As more interfaces move to voice-first, the bottleneck shifts from model architecture to data quality — which is exactly the problem this kind of pipeline is built to solve.