Artificial Intelligence
Why Is Apple Teaching an AI to Read Pictures of Text?
Apple’s LensVLM turns long documents into miniature page images, then expands only what matters. What 4.3× compression really…
Apple’s LensVLM turns long documents into miniature page images, then expands only what matters. What 4.3× compression really…
EmbeddingGemma becomes a local transcriber. What its 13-second demo reveals about word fidelity, small specialists, and enterprise voice…
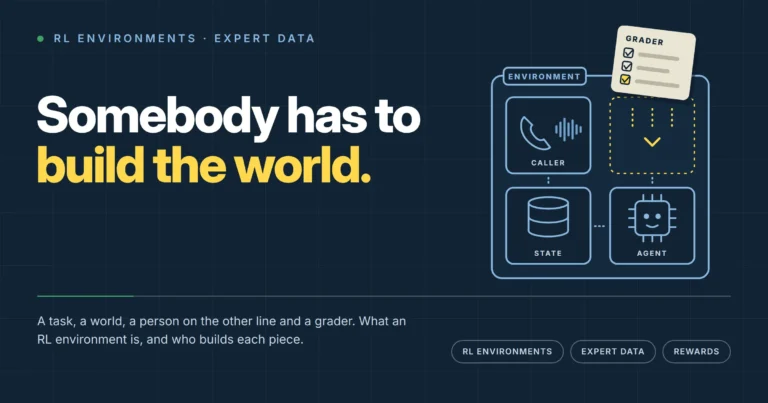
What is an RL environment? Follow one being built, from the operator who defines "done" to the callers,…
A cloned voice helped move €95m out of an Italian bank. Why voice deepfake detection fails on real…
Six AI labs shipped decision models in 17 days. How Jev and Cloudflare Clef return probabilities, not text,…
pass^k measures whether an AI agent succeeds on every repeated call: how to estimate it without bias, grade…
A model goes from 94% to 97%. How test leakage can inflate that gain, how contamination happens by…
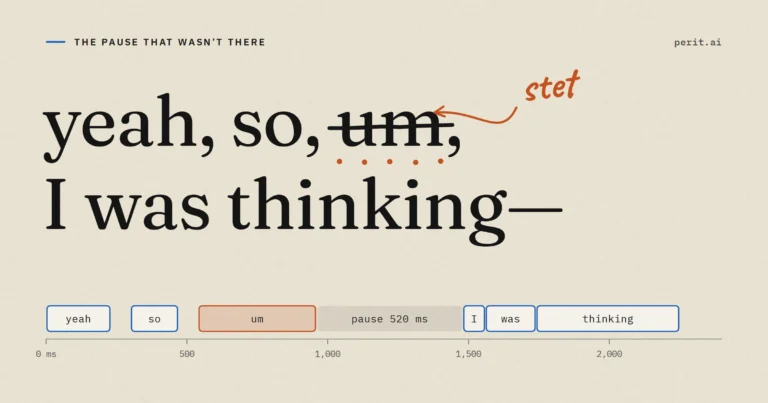
How transcription choices change word timestamps, where forced alignment fails on conversation, and what timing benchmarks reveal about…
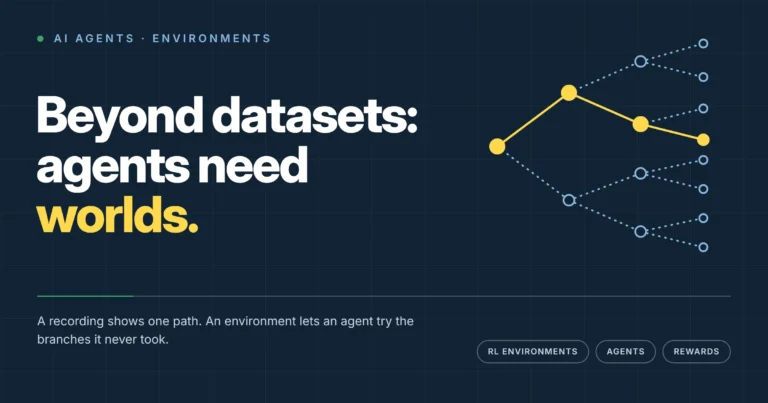
A recorded call shows one outcome. An RL environment lets a voice agent try other decisions, with real…
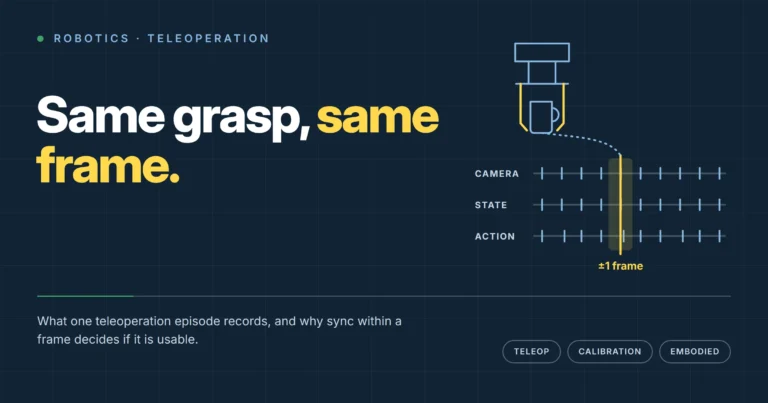
What a teleoperation episode records, how its streams stay synchronised, and why calibration and session metadata matter for…