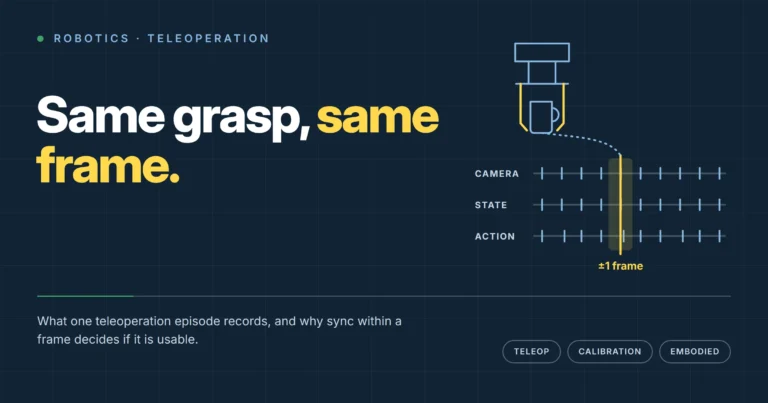
Featured Teleoperation Explained What a teleoperation episode records, how its streams stay synchronised, and why calibration and session metadata matter for… Sep 30, 2026 · 8 min read
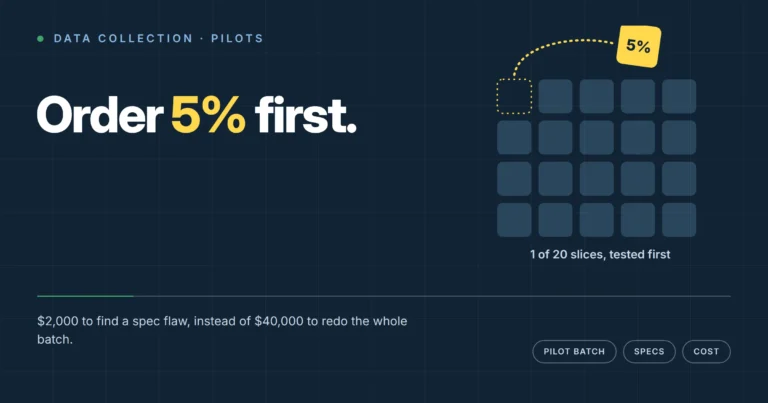
Featured Order 5% First: How a Data Collection Pilot Works A 5% pilot tests whether a data brief works before the full order runs. The cost arithmetic, what… Sep 29, 2026 · 8 min read
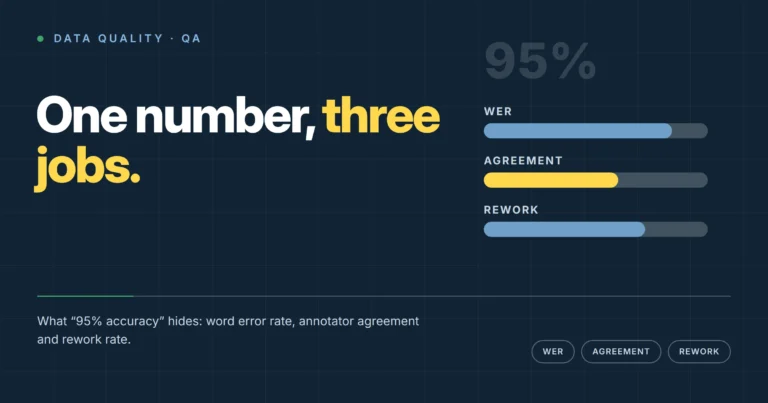
Guides What “95% Accuracy” Means in Data Annotation QA What QA-sample accuracy, word error rate, agreement and rework rate each tell you about an annotation batch. Sep 24, 2026 · 9 min read
Research Collection, Annotation or Both? Does a model failure need new inputs, better labels or a clearer spec? A guide to choosing data… Sep 20, 2026 · 14 min read
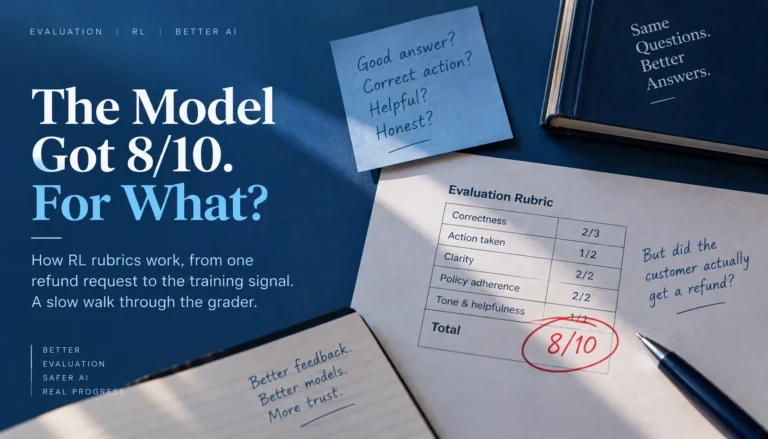
Tech Update The Model Got 8/10. For What? A refund answer earns eight out of ten, but no refund was submitted. How RL rubrics define success,… Sep 13, 2026 · 29 min read
Tech Update The AI Lab, the Vortex, and the 10,000-Agent Weekend OpenAI’s proposed forced-fluid proof, the search involving 10,000 agents, and the questions formal verification leaves about scientific credit. Sep 11, 2026 · 14 min read
Artificial Intelligence The Hardest Word in Voice AI Might Be “Yeah” “Yeah” can acknowledge a speaker or interrupt them. What TurnBench measures, where voice agents struggle, and how anticipation… Sep 6, 2026 · 11 min read